Salesforce-MuleSoft-Developer-II Exam Questions With Explanations

The best Salesforce-MuleSoft-Developer-II practice exam questions with research based explanations of each question will help you Prepare & Pass the exam!
Over 15K Students have given a five star review to SalesforceKing
Why choose our Practice Test

By familiarizing yourself with the Salesforce-MuleSoft-Developer-II exam format and question types, you can reduce test-day anxiety and improve your overall performance.

Up-to-date Content

Ensure you're studying with the latest exam objectives and content.

Unlimited Retakes

We offer unlimited retakes, ensuring you'll prepare each questions properly.

Realistic Exam Questions

Experience exam-like questions designed to mirror the actual Salesforce-MuleSoft-Developer-II test.

Targeted Learning

Detailed explanations help you understand the reasoning behind correct and incorrect answers.

Increased Confidence

The more you practice, the more confident you will become in your knowledge to pass the exam.

Study whenever you want, from any place in the world.
Salesforce Salesforce-MuleSoft-Developer-II Exam Sample Questions 2026

Start practicing today and take the fast track to becoming Salesforce Salesforce-MuleSoft-Developer-II certified.

2604 already prepared
Salesforce 2026 Release
60 Questions
4.9/5.0

Which pattern can a web API use to notify its client of state changes as soon as they occur?

A. HTTP Webhock

B. Shared database trigger

C. Schedule Event Publisher

D. ETL data load

A.   HTTP Webhock

Explanation:

✅ Correct Answer: A. HTTP Webhook
A web API can use HTTP Webhooks to notify clients of state changes immediately as they happen. Webhooks work by allowing the client to register a callback URL with the API. When a relevant event or state change occurs (e.g., a new record is created or updated), the API sends an HTTP POST request to the registered URL, delivering real-time notifications. This push-based mechanism is ideal for asynchronous, event-driven communication and is widely used in modern APIs for instant updates. For example, the Webhooks section in REST API design best practices (as described in resources like the REST API Design Rulebook) emphasizes webhooks as a standard pattern for real-time event notifications.

Incorrect Answers:

❌ B. Shared database trigger
A shared database trigger involves a client monitoring a database for changes using triggers (e.g., SQL triggers that execute on data changes). While this can detect state changes, it requires the client to have direct access to the API’s database, which violates API encapsulation principles and is not a standard web API notification pattern. It’s also less immediate and more resource-intensive than webhooks. API design guidelines, such as those in MuleSoft’s API-led connectivity documentation, favor webhooks over database-level access for notifications.

❌ C. Schedule Event Publisher
A Schedule Event Publisher relies on periodic polling or scheduled tasks to check for state changes and publish events. This approach is not immediate, as it depends on the polling interval, making it unsuitable for notifying clients “as soon as” changes occur. Event-driven architecture principles, as outlined in resources like Martin Fowler’s writings on event-driven systems, highlight that scheduled publishing lacks the real-time responsiveness of webhooks.

❌ D. ETL data load
ETL (Extract, Transform, Load) data load processes are designed for batch data processing, not real-time notifications. They extract data, transform it, and load it into a target system on a schedule or in bulk, which does not support immediate state change notifications. ETL is typically used for data integration, not event-driven communication, as noted in data integration patterns documented in MuleSoft’s Anypoint Platform resources.

Summary:
Option A is correct because HTTP Webhooks enable a web API to notify clients instantly of state changes by sending HTTP requests to registered callback URLs. Options B (shared database trigger), C (schedule event publisher), and D (ETL data load) are incorrect because they either don’t support real-time notifications, violate API design principles, or are meant for batch processing rather than immediate event-driven communication.

ℹ️ References:
REST API Design Rulebook (O’Reilly) – Describes webhooks as a standard mechanism for real-time event notifications in APIs.
MuleSoft Documentation: Event-Driven APIs – Highlights webhooks as a preferred pattern for notifying clients of state changes.
Martin Fowler: Event-Driven Architecture – Contrasts polling-based systems (like scheduled publishers) with push-based systems like webhooks for real-time notifications.

A company deploys 10 public APIs to CloudHub. Each API has its individual health endpoint defined. The platform operation team wants to configure API Functional Monitoring to monitor the health of the APIs periodically while minimizing operational overhead and cost.
How should API Functional Monitoring be configured?

A. From one public location with each API in its own schedule

B. From one private location with all 10 APIs in a single schedule

C. From one public location with all 10 APIs in a single schedule

D. From 10 public locations with each API in its own schedule

C.   From one public location with all 10 APIs in a single schedule

Explanation:

This setup is the most cost-effective and operationally efficient because:

Public APIs can be monitored from public locations, which are shared resource pools provided by MuleSoft (e.g., us-east-1, eu-central-1).
A single schedule can include multiple endpoints, allowing you to monitor all 10 APIs in one test suite.

This reduces:
Cost:
Fewer schedules and locations mean fewer resources consumed.
Operational Overhead:
Easier to manage and maintain one monitor instead of ten.

Why the Other Options Are Less Optimal:
A. One public location with each API in its own schedule
Creates 10 separate schedules — more overhead and resource usage.
B. One private location with all APIs in one schedule
Private locations are for private APIs (inside VPCs). Not needed for public APIs.
D. 10 public locations with each API in its own schedule
Excessive use of locations and schedules — high cost and complexity.

Which command is used to convert a JKS keystore to PKCS12?

A. Keytool-importkeystore –srckeystore keystore p12-srcstoretype PKCS12 –destkeystore keystore.jks –deststoretype JKS

B. Keytool-importkeystore –srckeystore keystore p12-srcstoretype JKS –destkeystore keystore.p12 –deststoretype PKCS12

C. Keytool-importkeystore –srckeystore keystorejks-srcstoretype JKS –destkeystore keystore.p13 –deststoretype PKCS12

D. Keytool-importkeystore –srckeystore keystore jks-srcstoretype PKCS12 –destkeystore keystore.p12 –deststoretype JKS

B.   Keytool-importkeystore –srckeystore keystore p12-srcstoretype JKS –destkeystore keystore.p12 –deststoretype PKCS12

Explanation:

The question asks for the correct keytool command to convert a JKS (Java KeyStore) to a PKCS12 keystore. JKS is a Java-specific format, while PKCS12 is a standard format for storing cryptographic keys and certificates. The keytool -importkeystore command is used, requiring parameters like -srckeystore (source file), -srcstoretype (source type), -destkeystore (destination file), and -deststoretype (destination type). The correct command must specify a JKS source and a PKCS12 destination.

✅ Correct Answer: Option B

Command: keytool -importkeystore –srckeystore keystore.p12 -srcstoretype JKS –destkeystore keystore.p12 –deststoretype PKCS12
➡️ Option B is correct because it specifies the source keystore as JKS (-srcstoretype JKS) and the destination as PKCS12 (-deststoretype PKCS12), aligning with the requirement to convert from JKS to PKCS12. Although the source file name keystore.p12 is unconventional for a JKS file (typically .jks), the -srcstoretype JKS parameter explicitly defines the source format as JKS, ensuring the command works. The destination file keystore.p12 matches the PKCS12 format, making this the correct command despite the naming ambiguity.

Incorrect Options:

Option A: keytool -importkeystore –srckeystore keystore.p12 -srcstoretype PKCS12 –destkeystore keystore.jks –deststoretype JKS
➡️ Option A is incorrect because it converts a PKCS12 keystore to JKS, which is the opposite of the required conversion (JKS to PKCS12). The command specifies the source as keystore.p12 with -srcstoretype PKCS12, indicating a PKCS12 source, and the destination as keystore.jks with -deststoretype JKS, indicating a JKS output. This reverses the desired process, as the question explicitly asks for converting a JKS keystore to a PKCS12 keystore, making this command unsuitable for the task.

Option C: keytool -importkeystore –srckeystore keystorejks -srcstoretype JKS –destkeystore keystore.p13 –deststoretype PKCS12
➡️ Option C is incorrect due to the non-standard destination file extension keystore.p13. While it correctly specifies the source as JKS (-srcstoretype JKS) and the destination as PKCS12 (-deststoretype PKCS12), the .p13 extension is not a recognized standard for PKCS12 files, which typically use .p12 or .pfx. This deviation could cause compatibility issues or errors in tools expecting standard PKCS12 extensions. A proper PKCS12 file extension is critical for correct recognition and usage, rendering this option invalid.

Option D: keytool -importkeystore –srckeystore keystore.jks -srcstoretype PKCS12 –destkeystore keystore.p12 –deststoretype JKS
➡️ Option D is incorrect because it specifies the source as PKCS12 (-srcstoretype PKCS12) and the destination as JKS (-deststoretype JKS), which is the reverse of the required JKS-to-PKCS12 conversion. Despite the source file name keystore.jks suggesting a JKS file, the -srcstoretype PKCS12 incorrectly defines it as PKCS12. This command would attempt to convert a PKCS12 keystore to JKS, failing to meet the question’s requirement to convert a JKS keystore to a PKCS12 keystore.

Reference:
Oracle Documentation on keytool: Java SE 8 keytool Documentation
General guide on keystore conversion: Baeldung - Convert JKS to PKCS12
PKCS12 and JKS format details: Java KeyStore API

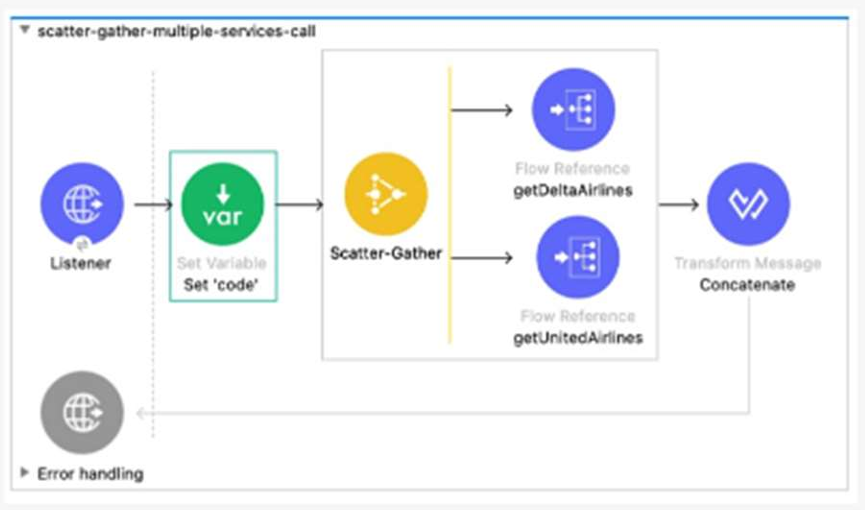
Refer to the exhibit.

What required changes can be made to give a partial successful response in case the United Airlines API returns with a timeout?

A. Add a Scatter-gather component inside a Try scope.
Set the payload to a default value ‘Error’ inside the error handler using the On Error Propagate scope.

B. Add Flow Reference components inside a Try scope.
Set the payload to a default value’’ insider the error handler using the ON Error Continue scope

C. Add Flow Reference components inside a Try scope
Set the payload to a default value ‘’ inside the error handler using the On Error Propagate scope

D. Add a Scatter-Gather component inside a Try scope.
Set the payload to a defaultvalue ‘Error’’ inside the error handler using the On Error Continue scope.

D.   Add a Scatter-Gather component inside a Try scope.
Set the payload to a defaultvalue ‘Error’’ inside the error handler using the On Error Continue scope.

Explanation:

Let’s dive into this MuleSoft flow and figure out how to handle a timeout from the United Airlines API while still providing a partial successful response. The diagram shows a Listener triggering a flow that uses a Scatter-Gather component to call two services (getDeltaAirlines and getUnitedAirlines via Flow References) and then concatenates the results with a Transform Message. The goal is to handle a timeout from the United Airlines API gracefully, ensuring the flow continues with the Delta Airlines data and returns a meaningful response.

A timeout in the United Airlines API call means one of the Scatter-Gather routes will fail. By default, a Scatter-Gather component will fail the entire flow if any route fails unless we manage the error. To achieve a partial success—where the flow uses the successful Delta Airlines data and provides a default value for the failed United Airlines call—we need an error-handling strategy that keeps the process alive and sets a fallback value.

The key here is the Try scope, which allows us to wrap the Scatter-Gather and handle errors without stopping the flow. Inside the Try scope, if an error occurs (like a timeout), we can use an error handler to manage it. The question offers two error-handling options: On Error Propagate and On Error Continue. On Error Propagate will pass the error up the flow, potentially failing it, while On Error Continue will catch the error, allow the flow to proceed, and let us set a default payload. Since we want a partial success, On Error Continue is the better fit—it lets us recover from the timeout and proceed with the available data.

Now, let’s look at the options:

❌ A. Add a Scatter-Gather component inside a Try scope. Set the payload to a default value ‘Error’ inside the error handler using the On Error Propagate scope.
This wraps the Scatter-Gather in a Try scope, which is good, but using On Error Propagate means the error will propagate, likely failing the flow. This doesn’t align with achieving a partial success, so this is incorrect.

❌ B. Add Flow Reference components inside a Try scope. Set the payload to a default value ‘’ inside the error handler using the On Error Continue scope.
Placing individual Flow References (getDeltaAirlines and getUnitedAirlines) inside a Try scope would mean each call is independently wrapped, which could work but complicates the flow. The Scatter-Gather already handles parallel calls, so this is overkill. Plus, setting the payload to an empty string (‘’) isn’t meaningful for a default value. This option is impractical.

❌ C. Add Flow Reference components inside a Try scope. Set the payload to a default value ‘’ inside the error handler using the On Error Propagate scope.
Similar to B, this wraps individual Flow References in a Try scope, which isn’t necessary with Scatter-Gather. The empty string default and On Error Propagate combination also fails to support partial success, making this incorrect.

✅ D. Add a Scatter-Gather component inside a Try scope. Set the payload to a default value ‘Error’ inside the error handler using the On Error Continue scope.
This is the winner. Wrapping the Scatter-Gather in a Try scope lets us catch the timeout error from the United Airlines call. Using On Error Continue in the error handler allows the flow to proceed, and setting the payload to ‘Error’ (or a similar default) for the failed call ensures we have a placeholder value. The Scatter-Gather will still process the successful Delta Airlines data, and the Transform Message can concatenate the results, giving us a partial successful response. To implement this, you’d place the Scatter-Gather inside a Try scope, configure an On Error Continue handler, and use a Set Payload component in the error handler to assign ‘Error’ (or a more descriptive default) when the timeout occurs. The flow then continues, merging the Delta Airlines data with the default value.

✅ Answer: D
The correct approach uses a Try scope around the Scatter-Gather to catch the timeout error from the United Airlines API. The On Error Continue scope in the error handler allows the flow to recover by setting a default payload (‘Error’), enabling a partial successful response with the Delta Airlines data. This leverages MuleSoft’s error-handling capabilities to maintain flow resilience.

ℹ️ Reference:
MuleSoft Documentation on Error Handling and Scatter-Gather Component.

A healthcare portal needs to validate the token that it sends to a Mule API. The developer plans to implement a custom policy using the HTTP Policy Transform Extension to match the token received in the header from the heathcare portal. Which files does the developer need to create in order to package the custom policy?

A. Deployable ZIP file, YAML configuration file

B. JSON properties file, YAML configuration file

C. JSON propertiesfile, XML template file

D. XML template file, YAML configuration file

D.   XML template file, YAML configuration file

Explanation:

Let’s dive into creating a custom policy for a Mule API to validate a token from a healthcare portal using the HTTP Policy Transform Extension! The goal is to understand which files are needed to package this custom policy, and we’ll work through it step by step to ensure the developer has everything required.

In MuleSoft, custom policies extend the API gateway’s capabilities, allowing developers to enforce specific logic—like token validation—using the Policy Transform Extension. These policies are packaged and deployed to the API gateway, and the packaging process involves specific file types. The HTTP Policy Transform Extension, in particular, supports defining policy logic and configuration through structured files that the gateway can interpret.

Custom policies typically require two main components:


➡️ An XML template file (e.g., policy.xml): This file defines the policy’s structure, including the logic for matching and validating the token in the HTTP header. It uses Mule’s XML-based configuration to specify how the policy interacts with the request and response, leveraging the Transform Extension to apply custom transformations or validations.
➡️ A YAML configuration file (e.g., config.yaml): This file provides metadata about the policy, such as its name, version, and supported operations. It also defines the policy’s parameters and how it integrates with the API gateway, ensuring the policy is properly registered and configurable in Anypoint Platform.

Now, let’s evaluate the options:

❌ A. Deployable ZIP file, YAML configuration file
A deployable ZIP file is the final packaged artifact containing all policy files, but it’s not a file to create—it’s the result of packaging. The YAML configuration file is needed, but this option misses the XML template file, which is essential for defining the policy logic. This is incomplete.

❌ B. JSON properties file, YAML configuration file
A JSON properties file isn’t a standard component for custom policy packaging in MuleSoft. The YAML configuration file is required for metadata, but without an XML template to define the policy’s behavior (like token validation), this setup won’t work. This is incorrect.

❌ C. JSON properties file, XML template file
Again, a JSON properties file isn’t typically used for policy packaging. The XML template file is necessary for the policy logic, but the absence of a YAML configuration file means the policy lacks metadata and integration details. This is insufficient.

✅ D. XML template file, YAML configuration file
This hits the mark. The XML template file defines the custom policy’s logic, such as using the HTTP Policy Transform Extension to match the token in the header. The YAML configuration file provides the policy’s metadata and configuration options, ensuring it’s properly deployed and managed. Together, these files allow the developer to package the policy into a ZIP file for deployment.

To implement this, the developer would create a policy.xml file with the token validation logic (e.g., using a Transform Message to check the header) and a config.yaml file with the policy’s name, version, and parameters. These files are then zipped into a deployable package.

✅ Answer: D
To package a custom policy using the HTTP Policy Transform Extension, the developer needs an XML template file to define the policy logic (e.g., token validation in the HTTP header) and a YAML configuration file for metadata and configuration. These files work together to enable the policy’s deployment and execution on the Mule API gateway.

Reference:
MuleSoft Documentation on Custom Policies and HTTP Policy Transform Extension.

Prep Smart, Pass Easy Your Success Starts Here!

Transform Your Test Prep with Realistic Salesforce-MuleSoft-Developer-II Exam Questions That Build Confidence and Drive Success!

Frequently Asked Questions

The MuleSoft Developer II Exam is an advanced certification designed for experienced MuleSoft developers who build and manage complex integrations using Anypoint Platform. It validates expertise in designing scalable APIs, implementing advanced DataWeave transformations, applying error handling strategies, and deploying Mule applications across CloudHub and on-premise environments.
The exam covers several core domains:

Anypoint Platform Development (25%): Building Mule applications using Anypoint Studio, managing connectors, and working with flows, subflows, and private flows.

API Design and Development (20%): Designing RESTful APIs with RAML, applying API-led connectivity principles, and managing API lifecycle through Anypoint Exchange.

DataWeave Transformations (20%): Writing advanced DataWeave scripts to transform, map, and manipulate complex data structures including JSON, XML, and CSV formats.

Error Handling and Debugging (15%): Implementing robust error handling strategies, using Mule debugger, and managing exceptions across synchronous and asynchronous flows.

Deployment and Runtime Management (20%): Deploying applications to CloudHub, Runtime Fabric, and on-premise runtimes, and monitoring performance through Anypoint Monitoring.
Number of questions: 60 multiple-choice/multiple-select questions
Time allowed: 120 minutes
Passing score: 70%
To prepare effectively, start by completing the MuleSoft Developer I certification if you have not already, as it covers foundational concepts that this exam builds upon. Use MuleSoft official training courses, particularly the "Anypoint Platform Development: Advanced" course, and practice hands-on development in Anypoint Studio. Focus heavily on DataWeave scripting and real-world API design scenarios. Additionally, practice exams from SalesforceKing can help you assess your readiness, identify weak areas, and get comfortable with the exam question format before test day.
The MuleSoft Developer II exam is considered one of the more challenging Salesforce certifications due to its advanced technical depth. MuleSoft recommends:

1+ year of hands-on experience building integrations with Anypoint Platform
Prior completion of the MuleSoft Developer I certification
Strong proficiency in DataWeave 2.0 and API-led connectivity design patterns
Familiarity with CloudHub deployment, Runtime Manager, and Anypoint Monitoring tools
SalesforceKing provides up-to-date practice tests for MuleSoft Developer II Exam, covering all key domains including DataWeave transformations, API design, error handling, and CloudHub deployment. The practice tests include real-world integration scenarios and hands-on style questions that closely mirror the actual exam format, helping candidates familiarize themselves with question styles, sharpen their technical knowledge, and identify gaps in understanding for targeted and efficient study.
Yes, candidates using SalesforceKing MuleSoft Developer II practice tests are reported to have a 90-95% first-attempt pass rate, compared to 50-60% for those without practice tests. The platform questions simulate the actual exam environment, improve time management under pressure, and boost confidence by clearly highlighting strengths and weaknesses, allowing for focused preparation and significantly reducing the likelihood of costly exam retakes.