Salesforce-MuleSoft-Platform-Integration-Architect Exam Questions With Explanations

The best Salesforce-MuleSoft-Platform-Integration-Architect practice exam questions with research based explanations of each question will help you Prepare & Pass the exam!
Over 15K Students have given a five star review to SalesforceKing
Why choose our Practice Test

By familiarizing yourself with the Salesforce-MuleSoft-Platform-Integration-Architect exam format and question types, you can reduce test-day anxiety and improve your overall performance.

Up-to-date Content

Ensure you're studying with the latest exam objectives and content.

Unlimited Retakes

We offer unlimited retakes, ensuring you'll prepare each questions properly.

Realistic Exam Questions

Experience exam-like questions designed to mirror the actual Salesforce-MuleSoft-Platform-Integration-Architect test.

Targeted Learning

Detailed explanations help you understand the reasoning behind correct and incorrect answers.

Increased Confidence

The more you practice, the more confident you will become in your knowledge to pass the exam.

Study whenever you want, from any place in the world.
Salesforce Salesforce-MuleSoft-Platform-Integration-Architect Exam Sample Questions 2026

Start practicing today and take the fast track to becoming Salesforce Salesforce-MuleSoft-Platform-Integration-Architect certified.

22734 already prepared
Salesforce 2026 Release
273 Questions
4.9/5.0

Refer to the exhibit.
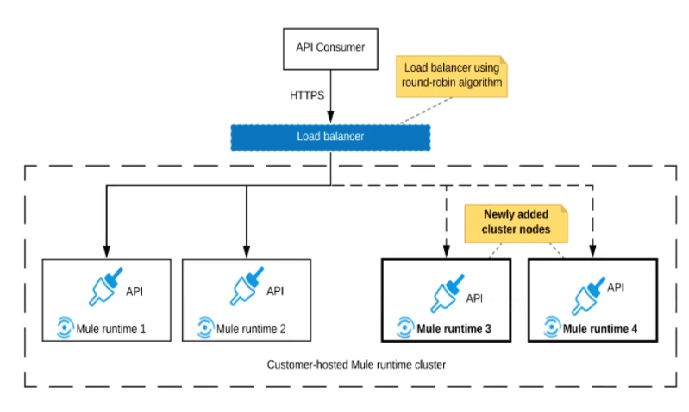
An organization uses a 2-node Mute runtime cluster to host one stateless API implementation. The API is accessed over HTTPS through a load balancer that uses round-robin for load distribution.
Two additional nodes have been added to the cluster and the load balancer has been configured to recognize the new nodes with no other change to the load balancer. What average performance change is guaranteed to happen, assuming all cluster nodes are fully operational?

A. 50% reduction in the response time of the API

B. 100% increase in the throughput of the API

C. 50% reduction In the JVM heap memory consumed by each node

D. 50% reduction In the number of requests being received by each node

D.   50% reduction In the number of requests being received by each node

Explanation
The key to this question is understanding how a stateless API and a round-robin load balancer behave when you add more nodes to a cluster.

Why D is Correct (50% reduction in requests per node):

Initial State:
2 nodes handling the total incoming request load (T). On average, each node handles T/2 requests.

New State:
4 nodes handling the same total incoming request load (T). With a round-robin algorithm, the load balancer will distribute requests evenly across all available nodes. Therefore, on average, each node now handles T/4 requests.

Calculation:
The number of requests per node has gone from T/2 to T/4. This is a 50% reduction ((T/2 - T/4) / (T/2) = 0.5).

Why A is Incorrect (50% reduction in response time):
Response time is determined by the application's logic, database calls, external integrations, and internal processing. Simply adding more nodes does not guarantee a proportional reduction in response time.

If the bottleneck is elsewhere (e.g., a slow database query or an external system with its own rate limit), the response time may not improve at all. Therefore, a specific performance improvement in response time is not guaranteed.

Why B is Incorrect (100% increase in throughput):
Throughput is the total number of requests the entire system can handle per unit of time. While adding nodes increases the capacity for higher throughput, it does not automatically increase the actual throughput.

The actual throughput is limited by the incoming client demand. If the client load (T) remains constant, the total system throughput remains the same; it's just distributed across more nodes. The system now has the potential for 100% higher throughput if the client load increases to match the new capacity, but this is not guaranteed by the scaling action alone.

Why C is Incorrect (50% reduction in JVM heap memory):
Heap memory consumption is driven by the application's behavior and the number of requests it is processing. While each node is now handling fewer requests, which might lead to lower memory usage, this is not a direct or guaranteed correlation.

The memory footprint of the Mule runtime itself and the application's baseline memory usage remain. There is no guarantee of a precise 50% reduction. Memory usage is highly dependent on the specific application and is not directly and linearly proportional to the number of nodes in this way.

Key References

Horizontal Scaling Principle:
The primary outcome of adding more nodes to a stateless system behind a load balancer is the distribution of the workload. The load per node is inversely proportional to the number of nodes, assuming a perfectly even distribution algorithm like round-robin.

MuleSoft Documentation:Clustering and High Availability
This documentation explains how clustering works to distribute load and provide high availability.

Concept: "A cluster is a group of Mule runtime servers that work together to achieve high availability and load balancing."

In summary, the only guaranteed outcome of adding two nodes to a two-node cluster for a stateless API behind a round-robin load balancer is that the average number of requests each individual node must process will be cut in half. The other options relate to performance (throughput, response time) or resource usage (memory), which are influenced by other factors and cannot be guaranteed to change by a specific percentage.

An insurance company has an existing API which is currently used by customers. API is deployed to customer hosted Mule runtime cluster. The load balancer that is used to access any APIs on the mule cluster is only configured to point to applications hosted on the server at port 443. Mule application team of a company attempted to deploy a second API using port 443 but the application will not start and checking logs shows an error indicating the address is already in use. Which steps must the organization take to resolve this error and allow customers to access both the API's?

A. Change the base path of the HTTP listener configuration in the second API to a different one from the first API

B. Set HTTP listener configuration in both API's to allow for connections from multiple ports

C. Move the HTTP listener configurations from the API's and package them in a mule domain project using port 443

D. Set the HTTP listener of the second API to use different port than the one used in the first API

C.   Move the HTTP listener configurations from the API's and package them in a mule domain project using port 443

Explanation
The issue arises because the Mule runtime cluster’s load balancer is configured to route traffic to applications on port 443, but deploying a second API with an HTTP listener on the same port (443) causes a conflict, resulting in the "address already in use" error. This happens because multiple applications cannot bind to the same port on the same server unless properly configured.

To resolve this and allow customers to access both APIs, the organization should use a Mule domain project. A domain project enables multiple Mule applications to share a common HTTP listener configuration, avoiding port conflicts. By defining a single HTTP listener on port 443 in the domain project, both APIs can share this listener, and the Mule runtime will route incoming requests to the appropriate API based on the request path. This approach ensures both APIs are accessible via the load balancer on port 443 without conflicts.

Why the other options are incorrect:

A. Change the base path of the HTTP listener configuration in the second API to a different one from the first API:
Changing the base path (e.g., /api/v1 vs. /api/v2) does not resolve the port conflict because the HTTP listener itself is still trying to bind to port 443, which is already in use by the first API.

B. Set HTTP listener configuration in both APIs to allow for connections from multiple ports:
Mule’s HTTP listener does not support binding to multiple ports in a single configuration, and the load balancer is only configured for port 443, so this option is not feasible.

D. Set the HTTP listener of the second API to use a different port than the one used in the first API:
Using a different port (e.g., 8081) for the second API would avoid the conflict, but the load balancer is only configured to route traffic to port 443. Customers would not be able to access the second API through the load balancer, making this solution impractical.

Reference

MuleSoft Documentation: Mule Domain Project. This explains how domain projects allow multiple applications to share resources like HTTP listeners, avoiding port conflicts.

MuleSoft Documentation: HTTP Connector. This details the configuration of HTTP listeners and their use in Mule applications.

MuleSoft Knowledge Base: Using Mule Domains for Shared Resources. This provides practical guidance on setting up shared HTTP listeners in a domain project.

An organization is evaluating using the CloudHub shared Load Balancer (SLB) vs creating a CloudHub dedicated load balancer (DLB). They are evaluating how this choice affects the various types of certificates used by CloudHub deplpoyed Mule applications, including MuleSoft-provided, customer-provided, or Mule application-provided certificates. What type of restrictions exist on the types of certificates that can be exposed by the CloudHub Shared Load Balancer (SLB) to external web clients over the public internet?

A. Only MuleSoft-provided certificates are exposed.

B. Only customer-provided wildcard certificates are exposed.

C. Only customer-provided self-signed certificates are exposed.

D. Only underlying Mule application certificates are exposed (pass-through)

A.   Only MuleSoft-provided certificates are exposed.

Explanation
The CloudHub Shared Load Balancer (SLB) is a multi-tenant service that terminates TLS/SSL for all applications running on the cloudhub.io domain. This architecture imposes a specific restriction on certificates.

Why A is Correct (Only MuleSoft-provided certificates):
When you use the Shared Load Balancer, your application's endpoint is [yourapp].us-east-1.cloudhub.io.

The TLS/SSL connection from the client is terminated at the Shared Load Balancer, not at your individual Mule application worker.

The certificate presented to the client for this *.cloudhub.io domain is issued and managed by MuleSoft. You, as a customer, cannot change this certificate.

Therefore, the only certificate ever exposed to external clients when using the SLB is the MuleSoft-provided certificate for the cloudhub.io domain.

Why the Other Options are Incorrect:

B. Only customer-provided wildcard certificates are exposed:
This is a capability of the Dedicated Load Balancer (DLB), not the Shared LB. With a DLB, you can associate your own custom domain and its corresponding certificate.

C. Only customer-provided self-signed certificates are exposed:
Self-signed certificates are not trusted by public clients and are never used for the public-facing endpoint of the Shared LB. They might be used for internal, non-public integrations behind the load balancer, but they are not exposed to the public internet.

D. Only underlying Mule application certificates are exposed (pass-through):
This describes a pass-through or TCP load balancing mode, which is a configuration option of the Dedicated Load Balancer. The Shared Load Balancer always operates in HTTPS termination mode, meaning it decrypts the traffic and does not pass the original TLS connection through to the worker.

Key References
MuleSoft Documentation: CloudHub Load Balancers

This documentation explicitly states the difference in certificate management between the shared and dedicated load balancers.

In summary, the primary restriction of the Shared Load Balancer is that it only exposes the MuleSoft-provided certificate for the cloudhub.io domain. To use a custom domain (e.g., api.mycompany.com) with your own certificate, you must provision and use a Dedicated Load Balancer.

When using Anypoint Platform across various lines of business with their own Anypoint Platform business groups, what configuration of Anypoint Platform is always performed at the organization level as opposed to at the business group level?

A. Environment setup

B. Identity management setup

C. Role and permission setup

D. Dedicated Load Balancer setup

B.   Identity management setup

Explanation:
The Anypoint Platform is structured in a hierarchy: Organization -> Business Groups -> Environments.

Organization Level:
This is the top-level container for your entire company's Anypoint Platform instance. Settings configured here apply to all business groups and users within the organization. The most fundamental of these is Identity Management.

Identity Management Setup:
This involves configuring how users authenticate to the platform (e.g., setting up Single Sign-On (SSO) with an identity provider like Okta, Azure AD, or PingFederate). This is an organization-wide setting. You cannot have one business group using username/password and another using SAML; the authentication method is unified for the entire organization. User directories and federation settings are managed at this top level.

Analysis of Other Options:

A. Environment setup:
Environments (like Design, Sandbox, Production) are created and managed within a specific Business Group. Different business groups can have their own sets of environments. This is not an organization-level configuration.

C. Role and permission setup:
While there are default organization-level roles, custom roles and permissions are defined at the Business Group level. A Business Group admin can create custom roles with specific permissions tailored to that group's needs. This provides autonomy to each line of business.

D. Dedicated Load Balancer setup:
A Dedicated Load Balancer (DLB) is provisioned and configured for a specific CloudHub environment, which resides within a Business Group. It is not an organization-level resource. Each business group's production environment, for example, could have its own DLB.

Key Concepts/References:

Anypoint Platform Hierarchy:
Understanding the scope of Organization, Business Groups, and Environments is crucial for access management and governance.

Centralized vs. Decentralized Control:
The organization level handles centralized, foundational settings that affect everyone (like authentication). Business groups are designed for decentralized control, allowing different divisions to manage their own APIs, applications, and user permissions.

Reference:
MuleSoft Documentation - Managing Organizations and Business Groups. The documentation clearly states that federated identity (a key part of Identity Management) is configured at the organization level.

An organization plans to extend its Mule APIs to the EU (Frankfurt) region.
Currently, all Mule applications are deployed to CloudHub 1.0 in the default North American region, from the North America control plane, following this naming convention: {APIname}—{ environment} (for example, Orderssapi—dev, Orders-sapi-—qa, Orders-sapi- —prod, etc.). There is no network restriction to block communications between APIs.
What strategy should be implemented in order to deploy the same Mule APIs to the CloudHub 1.0 EU region from the North America control plane, as well as to minimize latency between APIs and target users and systems in Europe?

A. In Runtime Manager, for each Mule application deployment, set the Region property to EU (Frankfurt) and reuse the same Mule application mame as in the North American region.
Communicate the new urls {API-name}—{environment}.de-ci.cloudhub.io to the consuming API clients In Europe.

B. In API Manager, set the Region property to EU (Frankfurt) to create an API proxy named {API-name}—proxy—{environment} for each Mule application.
Communicate the new url {API-name}—proxy—{environment}.de-c1.cloudhub.io to the consuming API clients In Europe.

C. In Runtime Manager, for each Mule application deployment, leave the Region property blank (default) and change the Mule application name to {API-name}— {environment).de-cl.
Communicate the new urls {API-name}—{environment}.de-ci1.cloudhub.io to the consuming API clients in Europe.

D. In API Manager, leave the Region property blank (default) to deploy an API proxy named {API-name}~proxy~- (environment}.de-cl for each Mule application.
Communicate the new url {API-name}—proxy—{environment}.de-cl.cloudhub.io to the consuming API clients in Europe.

A.   In Runtime Manager, for each Mule application deployment, set the Region property to EU (Frankfurt) and reuse the same Mule application mame as in the North American region.
Communicate the new urls {API-name}—{environment}.de-ci.cloudhub.io to the consuming API clients In Europe.

Explanation:
The goal is to deploy the same Mule applications to the EU region to reduce latency for European users, while managing everything from the existing North America control plane.

Why A is Correct:
This is the standard and direct method for deploying a Mule application to a specific CloudHub region.

Deployment in Runtime Manager:
You deploy the application through Runtime Manager (part of the North America control plane) and explicitly select the EU (Frankfurt) region from the "Region" dropdown during deployment.

Application Name:
The application name (Orders-api-dev) is an identifier within Runtime Manager and can be reused across different regions because the fully qualified domain name (FQDN) is unique. The FQDN is determined by the region, not just the app name.

URL for EU Clients:
Applications deployed to the EU (Frankfurt) region receive the domain suffix .de-ci.cloudhub.io. Therefore, the endpoint for European clients would be orders-api-dev.de-ci.cloudhub.io. This endpoint is hosted on infrastructure in Frankfurt, minimizing latency for users and systems in Europe.

This approach meets both requirements: deploying to the EU region from the NA control plane and minimizing latency.

Why the Other Options Are Incorrect:

B. In API Manager, set the Region property to EU (Frankfurt) to create an API proxy...:
This is incorrect because API Manager does not deploy Mule applications. API Manager is used to create API proxies that are applied to already-deployed applications. The "Region" setting in API Manager is for selecting which regional API gateway (US or EU) will host the proxy, not for deploying the underlying Mule runtime. The Mule application itself must be deployed to the EU region via Runtime Manager first.

C. ...change the Mule application name to {API-name}— {environment).de-cl:
This is unnecessary and incorrect. You cannot force an application into a region by adding a region code to its name. The region is a separate, explicit property set during deployment in Runtime Manager. The application name is a logical identifier and should remain consistent. The platform automatically assigns the correct domain based on the selected region.

D. In API Manager, leave the Region property blank...:
This option has the same fundamental flaw as B. It suggests that API Manager is the tool for deployment, which it is not. Furthermore, leaving the region blank would default to the US gateway, which would not help reduce latency for European users. The traffic would still be proxied through the US.

Reference:
MuleSoft Documentation: Deploying a Mule Application to CloudHub - The process involves selecting a target region in Runtime Manager.

MuleSoft Documentation: CloudHub Regional Deployments - Explains that you manage deployments to different regions from a single control plane and that each region has a different domain suffix (e.g., .us-e2.cloudhub.io for US, .de-ci.cloudhub.io for EU).

Conclusion: To deploy Mule applications to a specific CloudHub region, you use Runtime Manager and select the target region. The application name itself is independent of the region. The correct endpoint URL is constructed by the platform as {app-name}.{region-code}.cloudhub.io.

Prep Smart, Pass Easy Your Success Starts Here!

Transform Your Test Prep with Realistic Salesforce-MuleSoft-Platform-Integration-Architect Exam Questions That Build Confidence and Drive Success!